
Restart without losing work
You restart AgentX after an update or a settings change. Agents may be in the middle of a task at that moment: answering a message, reviewing a merge request, running a scheduled job.
When AgentX is asked to stop, it now:
- Stops taking new work. Messages and scheduled jobs wait; anything that asks it to start a task gets "restarting, try again shortly".
- Lets the tasks already running finish, for up to 5 minutes.
- Writes one line to its log saying why it stopped and how many tasks were running.
- Exits.
This page shows how to restart so that this works, including when AgentX runs as a background service.
The daemon is the AgentX program that keeps running in the background. It can be started three ways, and the restart command works with each:
- by launchd, the Mac's built-in service manager (a
.plistsettings file in~/Library/LaunchAgents/), - by systemd, the Linux service manager (an
agentx.serviceunit), - or by hand, with
agentx daemon start --detach.
Restart when no task is running (recommended)
Use this after an update, and in deploy scripts, instead of launchctl kickstart -k or systemctl restart.
- Terminal: go to the folder that holds
agentx.json. - Terminal: run:sh
agentx daemon restart --when-idle - Read what it prints. It names the service manager it found, then:
Waiting: 2 task(s) running...while agents are still busy. It checks every 5 seconds.No tasks running.once it has seen zero running tasks twice in a row.Daemon is back (PID …) after 4s.when the new daemon answers. The command only reports success at this point.
It waits up to 30 minutes. If tasks are still running after that, it restarts anyway and says so. Those tasks still get the usual time to finish, and anything cut off is picked up again after the restart (see below).
Options:
| Option | What it does |
|---|---|
--timeout <minutes> | Wait this long instead of 30 minutes. |
--abort-on-timeout | When the wait runs out, don't restart. The command exits with an error and AgentX keeps running. Use this in deploy scripts that can try again later. |
--interval <seconds> | How often to check. The default is 5. |
--reload-service | Also re-read the service's settings file. Use it after you edit the .plist or the systemd unit. |
--dry-run | Show what it would run, without restarting. |
Without --when-idle, the restart starts right away. Running tasks still get the usual time to finish.
What it runs
| AgentX runs under | The command |
|---|---|
| launchd | Asks launchd to stop AgentX, waits for it to exit, then starts the job again. With --reload-service, it unloads the job, waits until launchd has let it go, then loads the .plist again. |
| systemd, system unit | systemctl restart <unit>. When you are not root, it uses sudo, which may ask for your password. Without a terminal it won't ask. If sudo needs a password, it stops and prints the exact command to run. |
| systemd, user unit | systemctl --user restart <unit>. No sudo. |
| Started by hand | Stops the daemon, waits until it has exited, then runs agentx daemon start --detach in the same folder. |
If a step fails before AgentX was stopped, it stays running and the command prints how to restart it by hand. agentx daemon deploy <host> --restart runs this same command on the other machine.
Restart from the dashboard
The dashboard can ask a node to restart itself as soon as no task is running. This needs launchd or systemd, because a service manager has to start AgentX again after it exits. On a daemon started by hand, use the terminal command above.
Browser: open the dashboard and select Live in the Hub's nav (under More on a phone).
Browser: under Machines, find the node's card, then select Restart when idle.
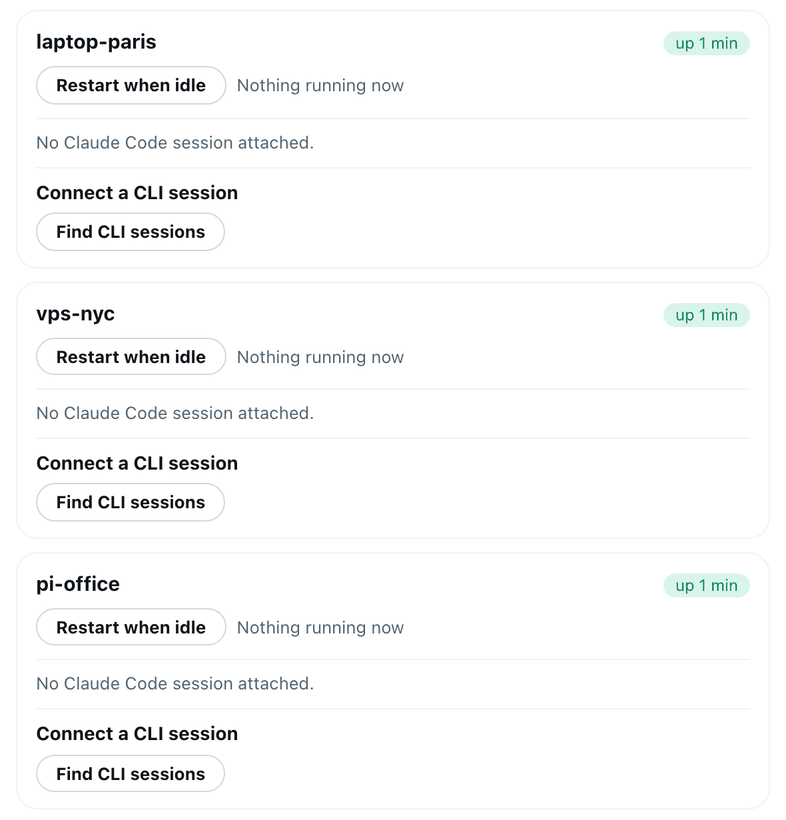
Browser: the button reads Restart once idle?. Select it again within a few seconds to confirm.
The card shows Restart waiting · 2 running · until 14:30 while it waits. To call it off, select Cancel restart.
When no task is running, it shows Restarting…, is unreachable for a few seconds, then comes back up.
The node waits up to 30 minutes, then restarts anyway. It refuses straight away, with a message saying why, when nothing would start it again:
- It was started by hand.
- On a Mac, the
.plisthas noKeepAlive, or sets it tofalse. - On Linux, the unit has
Restart=no(the default),on-abnormal,on-abortoron-watchdog. SetRestart=alwaysto use the button.
With Restart=on-failure, or a Mac KeepAlive that only restarts after a failed exit, AgentX exits with code 75 so that the service manager starts it again.
Only you can use the button: the dashboard asks for its key (dashboard.token) when one is set, and the node takes the request only from the same machine or from another node with its mesh token. Pages from other websites are refused.
Stop and start by hand
- Terminal: stop the daemon. The command waits until running tasks have finished:shIf tasks are running, it says so and waits. It prints
agentx daemon stopDaemon stoppedwhen it's done. - Terminal: start it again:sh
agentx daemon start --detach
Don't start the daemon again before stop has finished: two daemons would compete for the same port.
Give a background service enough time
If AgentX runs as a service that the system starts for you, the system decides how long to wait before forcing it closed. Its default is shorter than AgentX needs, so set it once.
On Linux (systemd):
- Terminal: open an override file for the service (named
agentxhere; use your service's name):shsudo systemctl edit agentx - Add these lines, then save:ini
[Service] TimeoutStopSec=360 KillMode=mixedTimeoutStopSecgives AgentX 6 minutes to finish.KillMode=mixedsends the stop request to AgentX only. Without it, systemd also stops the agents' own programs at the same moment, and the running tasks fail straight away. - Terminal: reload systemd's settings:sh
sudo systemctl daemon-reload
On a Mac (launchd):
- Terminal: open the service's settings file in
~/Library/LaunchAgents/(for examplecom.example.agentx.plist). - Add this inside the main
<dict>:xmlWithout it, macOS forces AgentX closed after about 20 seconds.<key>ExitTimeOut</key> <integer>360</integer> - Terminal: reload the service so the setting applies:shThis unloads the job, waits until macOS has let it go, then loads the settings file again. Running the two
agentx daemon restart --when-idle --reload-servicelaunchctlcommands back to back can fail, because the second one runs before the first has finished, and AgentX then stays stopped.
Change how long it waits
The daemon waits up to 5 minutes for running tasks. To change that for every agent:
- Terminal: in the folder with
agentx.json, set the wait in seconds:shagentx config set shutdown.drainTimeoutSeconds 600 - Raise the service's stop time to at least a minute longer (
TimeoutStopSecorExitTimeOut, as above), or the system will force AgentX closed first.
Some agents do work that takes much longer, such as rendering a video. You can give only those agents more time, and keep the short wait for the rest:
- Terminal: set the agent's own wait, in seconds (here for an agent named
editor):shagentx config set agents.editor.drainTimeoutSeconds 1800 - Raise the service's stop time above the longest of these waits.
A stop then waits as long as the longest wait among the agents that are still busy. An agent's own wait can make a stop longer, never shorter.
The older AGENTX_DRAIN_TIMEOUT_MS setting (in milliseconds, in the .env file next to agentx.json) still works. It is used only when shutdown.drainTimeoutSeconds is not set.
A task still running when the wait ends is stopped. It reports killed by daemon restart (drain limit …s, requested by …), not a time limit of its own, and nothing is posted to its chat. When AgentX starts again, the task is picked up again or reported, as described below.
Hold restart requests, or give them a daily time
A deploy script can ask for "restart when idle" and, after the wait, restart anyway. If your agents do long work, such as rendering a video, that wait cuts it off. You can make AgentX refuse that, and hold requests from anyone but named requesters until a quiet hour:
- Terminal: in the folder with
agentx.json, allow only the requesters you name (a regular expression matched against the request'sby), and pick the daily time at which everyone else's request runs:shagentx config set shutdown.restart.allowBy '^(operator|restart-window)' agentx config set shutdown.restart.window 03:00 - Terminal: make every request idle-only, so a wait that runs out gives up instead of restarting:sh
agentx config set shutdown.restart.forbidOnTimeoutRestart true - Restart AgentX once (at a quiet moment) so it reads the new settings.
From then on, a request from a deploy script gets the reply state: "deferred" with the time it will run, and the dashboard shows it as waiting. At that time AgentX waits up to windowWaitMinutes (3 hours by default) for a moment with no task running, then restarts; if that moment never comes, it gives up and nothing is cut off. A request from a requester you named runs at once, as before. Without a window, held requests are refused with HTTP 403.
Every reply to POST /daemon/restart, and GET /daemon/restart, now lists the tasks a restart would cut off, with the agent, the chat, the step and how long each has been running, so a deploy script can decide for itself.
Work that gets cut off anyway
Some work still gets cut off: a task that runs longer than the wait, a crash, or a machine that loses power. When AgentX starts again, it looks at every task that was cut off and decides what to do with each one:
| The task came from | What happens |
|---|---|
| A chat (Telegram, WhatsApp, GitLab, GitHub, Slack…) in the last 30 minutes | It's picked up again. The chat gets a short note first: "AgentX restarted while working on this. Picking it up again." The answer arrives in the same chat. |
| A chat another node received and passed to this one (a GitLab event that arrives on your server, for an agent that lives on your Mac) | It's picked up again, and the note and the answer are posted through the node that received it. Both nodes need this version; if that node is down, you get the "didn't resume" message instead. |
| A scheduled job | Nothing. The next scheduled run does the work. |
| A workflow step | Reported. The workflow decides whether to retry. |
| A step of a request's plan | The step is not blocked. Within a minute of the restart, the plan hands it to its agent again, as agentx requests step <id> <step> --retry would. You are not told. |
| One agent asking another, when the run knows which agent asked | It's picked up again, and the answer is handed to the agent that asked, as a new turn, with a note saying the work was cut off and run again. That agent then decides what to do with it. |
| Anything else (voice, webhooks, the API) | Reported, because nothing would deliver the answer. |
| Anything older than 30 minutes | Reported. |
"Reported" means the task isn't run again. Its chat gets a note saying so, or, when there's no chat, you get one message listing them (at notifications.destination).
A task that is picked up again is told it was interrupted, along with the steps it had already taken, and asked to check before repeating anything that affects the outside world, such as posting a message, pushing code or deploying.
Helpers that a restart stops
An agent can hand part of a task to a helper that works in the background, for example a builder that writes code in its own copy of a project (a "clone"). Helpers run inside the agent's task, so a restart stops them too, and they are not started again. Their unsaved changes stay in their folders.
When AgentX starts again, it looks at every folder the cut-off task named in its steps. For each folder that is tracked by git and still holds changes that were never committed (saved in git), or commits that were never pushed (sent to the shared copy), it lists the folder, its branch, and what is unsaved:
- The task is picked up again: the agent is told which helpers were stopped and which folders still hold unsaved work, so it can finish that work instead of starting over. It is asked to check first that the work is its own, because a shared folder can hold someone else's changes.
- The task is not picked up: you get the list in the message at
notifications.destination, under "These folders still hold unsaved work".
Either way, each folder is also written to the log, in a line like [resume] dev-agent t1: unsaved work in /tmp/app-12 (branch 12-new-form): 3 changed files not committed.
Each folder is shown the way the task named it. On a Mac, /tmp/app-12 stays /tmp/app-12, even though the Mac stores it under /private/tmp. Folders with nothing unsaved are left out. AgentX only reads the folders; it never commits, pushes or deletes anything in them.
To stay safe, AgentX never picks the same task up twice:
- A task cut off again while being picked up is reported, not retried.
- After 3 restarts within 10 minutes, it stops picking tasks up and reports them instead. A task that keeps crashing AgentX can't keep doing so.
Change what gets picked up
Set these in agentx.json under resume. Every value shown is the default:
"resume": {
  "enabled": true,
  "maxAgeMinutes": 30,
  "maxAttempts": 1,
  "reportOnlyChannels": [],
  "directChannels": [],
  "crashLoop": { "restarts": 3, "windowMinutes": 10 }
}reportOnlyChannels: chats whose tasks are only reported, never picked up. For example["gitlab"].directChannels: non-chat sources to pick up anyway, such as["voice"]. Their answer isn't delivered anywhere; only the work gets done. Add a source only when the work is what matters."enabled": falseturns picking up off; everything is reported.
Work that runs past its time limit
Each agent has a time limit for one run, maxExecutionMinutes (20 minutes unless you change it). When a run passes it, AgentX stops the run. It then picks the work up once more in the same conversation. The agent is told that it hit its time limit, and which steps it had already taken. It is asked to finish, or to say what is done, what is left and what is blocking it. The answer goes to whoever asked, as usual.
The same exceptions apply as after a restart:
| The run came from | What happens |
|---|---|
| A chat, the API, or one agent asking another | It's picked up once more. |
| A scheduled job | It ends with the time-limit error. The next scheduled run does the work. |
| A workflow step | It ends with the time-limit error. The workflow decides whether to retry. |
| Another node (the agent lives there) | That node picks it up itself. |
When the run is not picked up again, its error says why, for example Claude Code timed out after 30m. … It was not continued (already continued once).
When one agent sends work to an agent on this machine, the sender waits long enough for the extra run: the time limit once more for each pick-up.
Set it in agentx.json under resume. The values shown are the defaults:
"resume": {
  "timeLimit": { "enabled": true, "maxContinuations": 1 }
}maxContinuations: how many times one request is picked up again after its time limit, from 0 to 3."enabled": falseturns it off: a run that passes its time limit ends with the error, as before.
If a kind of task always needs longer, raise the agent's maxExecutionMinutes instead.
Check it worked
To check the restart command:
- Terminal: while an agent is working on something, run
agentx daemon restart --when-idle. - It prints
Waiting: 1 task(s) running..., thenNo tasks running.once the agent has answered. - It ends with
Daemon is back (PID …) after …s. - Terminal:
agentx daemon logsshowsShutdown: SIGTERM requested by agentx daemon restart (…); 0 task(s) in flight; …
To check the dashboard button:
- Browser: on the Hub's Live page, select Restart when idle on a machine's card, then Restart once idle?.
- The card shows Restart waiting, then Restarting…, then up again.
- Terminal: on that node,
agentx daemon logsshowsRestart when idle: no tasks running, thenShutdown: restart requested by restart-when-idle from the dashboard (…).
To check which version is running after an update:
- Terminal: ask the daemon (use your
node.bindaddress):shcurl -s http://127.0.0.1:18800/health - Read three values near the top of the answer:
version: the AgentX version the daemon is running, for example"0.61.0".commit: a short code that identifies the exact build, ornullwhen AgentX was built outside a git folder or runs straight from source. If it ends in-dirty, the build had local changes, so it doesn't match that commit exactly.startedAt: when this daemon started.
- These describe the program that is running, not the files on disk. If
versionis still the old one, orstartedAtis older than your update, the daemon hasn't restarted yet: restart it as above.
To check a plain stop:
- Terminal: while an agent is working on something, run
agentx daemon stop. - Terminal: open the log with
agentx daemon logs. You should see, in order:Shutdown: SIGTERM requested by agentx daemon stop (…); 1 task(s) in flight; …Draining 1 in-flight task(s) …Drain complete (…ms)
- The agent's answer arrives as usual, and
stopprintsDaemon stopped.
To check that cut-off work is picked up:
- Terminal: while an agent is answering a chat message, force AgentX closed, for example with
kill -9on the daemon's process. - Terminal: start the daemon again.
- Within a few seconds the chat shows the "Picking it up again" note, then the answer.
- Terminal:
agentx daemon logsshowsResume: 1 resumed, 0 reported, 0 skipped, 0 failed.
To check that a stopped helper's work is listed:
- Terminal: ask an agent to start a background helper that changes a file in a git folder, such as
/tmp/app-12, without committing. - Terminal: while the helper works, force AgentX closed (
kill -9on the daemon's process), then start it again. - Terminal:
agentx daemon logsshows[resume] … unsaved work in /tmp/app-12 (branch …): 1 changed file not committed.
To check that work past its time limit is picked up:
- Terminal: on a test agent, set
maxExecutionMinutesto1inagentx.json. - Browser or chat: ask that agent for something that takes a few minutes.
- Terminal: after a minute,
agentx daemon logsshows[resume] … stopped at its 1m time limit; continuing (1/1). - The answer arrives in the same chat. If the second run hits the limit too, the error ends with
It was not continued (already continued once). - Terminal: set
maxExecutionMinutesback.
A restart by systemd or launchd shows from systemd or from launchd (…) in the first line, instead of requested by.
If something is wrong
restartsaysThe daemon is not answering: AgentX isn't running, or listens on another address. Checknode.bindinagentx.json, then start it withagentx daemon start --detachor through its service.restartstops and prints asudo systemctl restart …command:sudoneeded a password and no terminal was attached. AgentX is still running. Run the printed command yourself, or allow that one command insudoers.restartsaysThe daemon did not come back within 2 min: the new daemon didn't start. Run theStart it with:command it printed, then readagentx daemon logs.restart --abort-on-timeoutexited withNot restarting: tasks were still running when the wait ran out. Try again later, or raise--timeout.- The dashboard says
would not start AgentX again: setKeepAlivetotruein the.plist, orRestart=alwayson the unit, as the message says. Or useagentx daemon restart --when-idlein a terminal. - The dashboard has no Restart when idle button: the node runs an older AgentX. Update it first.
- The restart button gives
401for another node: the dashboard needs that node's mesh token indashboard.daemons. - Tasks still fail right away on a Linux service: check
systemctl show -p KillMode agentx. It must saymixed. - The log shows no
Shutdown:line at all: the system forced AgentX closed before it could start. RaiseTimeoutStopSecorExitTimeOutas above. Drain timeout after … task(s) still in flight: a task took longer than the wait and was stopped. The next line,Interrupted … run(s): killed by daemon restart (…), says which limit applied and who asked for the restart. Raiseshutdown.drainTimeoutSeconds, or the busy agent's owndrainTimeoutSeconds, and the service's stop time with it.- A task says
timed out after 90malthough it ran for a few minutes: the daemon that ran it is older than this fix. After an update, a task a restart cuts off sayskilled by daemon restartinstead. stopsays the daemon is still finishing tasks: wait, then check withagentx daemon statusbefore starting it again.- Another tool got
503 daemon is restarting: it asked for new work during a restart. It can try again a little later. - A chat task wasn't picked up: the log line starting
[resume]says why. The usual reasons are that it was older than 30 minutes, it was already a second attempt, or there were several restarts in a row. - A helper's work isn't listed after a restart: AgentX only finds folders the task named in its steps, such as
cd /tmp/app-12. A folder the helper never named, or one that isn't tracked by git, can't be found. Look for it by hand, and ask agents to work in a folder they name in their commands. - A plan step shows blocked with
killed by daemon restart: it was cut off by a version from before this change. Runagentx requests step <id> <step> --retry. Newer versions hand such a step back on their own; the daemon log sayscut by a restart; handed to it again after the restart, orcut by a crash; …when the daemon stopped without a drain (a crash,kill -9, a power cut). - A task that passed its time limit wasn't picked up again: the log line
[resume] … not continued — …says why: it was a scheduled job or a workflow step, it had already been picked up once, or the caller's own time limit left no time. Raise the agent'smaxExecutionMinutesif the task always needs longer. - You got a "didn't resume" message you didn't expect: that task came from somewhere with no chat to answer in. Send the request again, or add its source to
directChannels.